As of 15 November 2026, every current Claude model has a 1 million token context window: Fable 5.2, Opus 5.5, Sonnet 5.5 and Haiku 5.5. A request can also return up to 128K tokens of output. On the API there is no beta header to set, and on Fable 5.2, Opus 5.5 and Sonnet 5.5 a long prompt costs the same per token as a short one. The one exception is Haiku 5.5, which charges more once a prompt passes 100,000 tokens.
That is the short answer. The useful question for a WordPress developer is narrower: what can you actually put in 1M tokens, and is it worth doing? We measured real plugins and WordPress core on 15 November 2026 to answer the first part, and worked out the bill for the second. The result is less flattering than the claims we made in March, and we correct those below.
Checked on 15 Nov 2026 against the Claude models overview, context windows page, pricing page and prompt caching page on platform.claude.com. Prices and limits change, so confirm them before you budget.
How big is Claude’s context window now?
1M tokens on all four current models, with 128K tokens of maximum output per request. Anthropic’s models overview lists the lineup like this.
Model | API ID | Context | Input / output per MTok |
|---|---|---|---|
Claude Fable 5.2 | claude-fable-5-2 | 1M tokens | $8 / $40 |
Claude Opus 5.5 | claude-opus-5-5 | 1M tokens | $4 / $20 |
Claude Sonnet 5.5 | claude-sonnet-5-5 | 1M tokens | $2 / $10 |
Claude Haiku 5.5 | claude-haiku-5-5 | 1M tokens | from $0.10 / from $0.50 |
Older models matter if your tooling pins one. Opus 5, Opus 4.8, Opus 4.7, Opus 4.6, Sonnet 5 and Sonnet 4.6 also have 1M. Opus 4.5, Sonnet 4.5 and Haiku 4.5 stop at 200K tokens.
One number from that page changes how you plan. The docs say 1M tokens is roughly 555,000 words, or 2.5 million characters, on the current tokenizer. Models before Opus 4.7 fit about 750,000 words in the same space. Our March version of this post used the 750,000 figure. It was right for the old tokenizer and is too generous now. The pricing page adds that the newer tokenizer produces about 30% more tokens for the same text than the one used by Sonnet 4.6 and earlier.
Which Claude models and plans get 1M tokens?
It depends on where you use Claude, not only on the model.
- Claude API: 1M is the default on every model that supports it. No header, no opt-in. The context windows page says so directly.
- Claude Code: Anthropic’s help article lists 1M for Fable 5.2, Fable 5.1, Fable 5, Opus 5.5, Opus 5, Opus 4.8, Opus 4.7, Opus 4.6, Sonnet 5.5, Sonnet 5, Sonnet 4.6 and Haiku 5.5. You pick the 1M variant with the model selector, and for older models with a suffix such as
[1m]. - Claude.ai chat on paid plans: the same article gives 1M for Fable 5.2, Fable 5.1, Opus 5.5, Opus 5, Sonnet 5.5, Sonnet 5 and Haiku 5.5. Fable 5, Opus 4.8, Opus 4.7, Opus 4.6 and Sonnet 4.6 get 500K in chat.
- Pro plan: the article says usage credits must be enabled on Pro to reach 1M on Opus 4.6 and Sonnet 4.6. It does not state a Pro restriction for the newer models, so check what your own model picker offers.
The practical point: “Claude has 1M tokens” and “my session has 1M tokens” are two different statements. Check the model name in your tool, not the marketing line.
What fits in 1M tokens: a WordPress plugin codebase?
A small to mid-size plugin fits. A large one does not. We measured instead of guessing.
We packed each plugin with the script further down: PHP, JS, CSS and readme.txt, skipping vendor, node_modules, tests, build output and minified files. Then we converted bytes to tokens with the Anthropic ratio of 2.5 characters per token. That ratio comes from the docs and describes ordinary text. Code can tokenize denser or looser, so treat the right-hand column as a planning estimate. For an exact number, send the packed file to the token counting API.
Codebase (version, 15 Nov 2026) | Packed size | Tokens at 2.5 chars/token | Fits in 1M? |
|---|---|---|---|
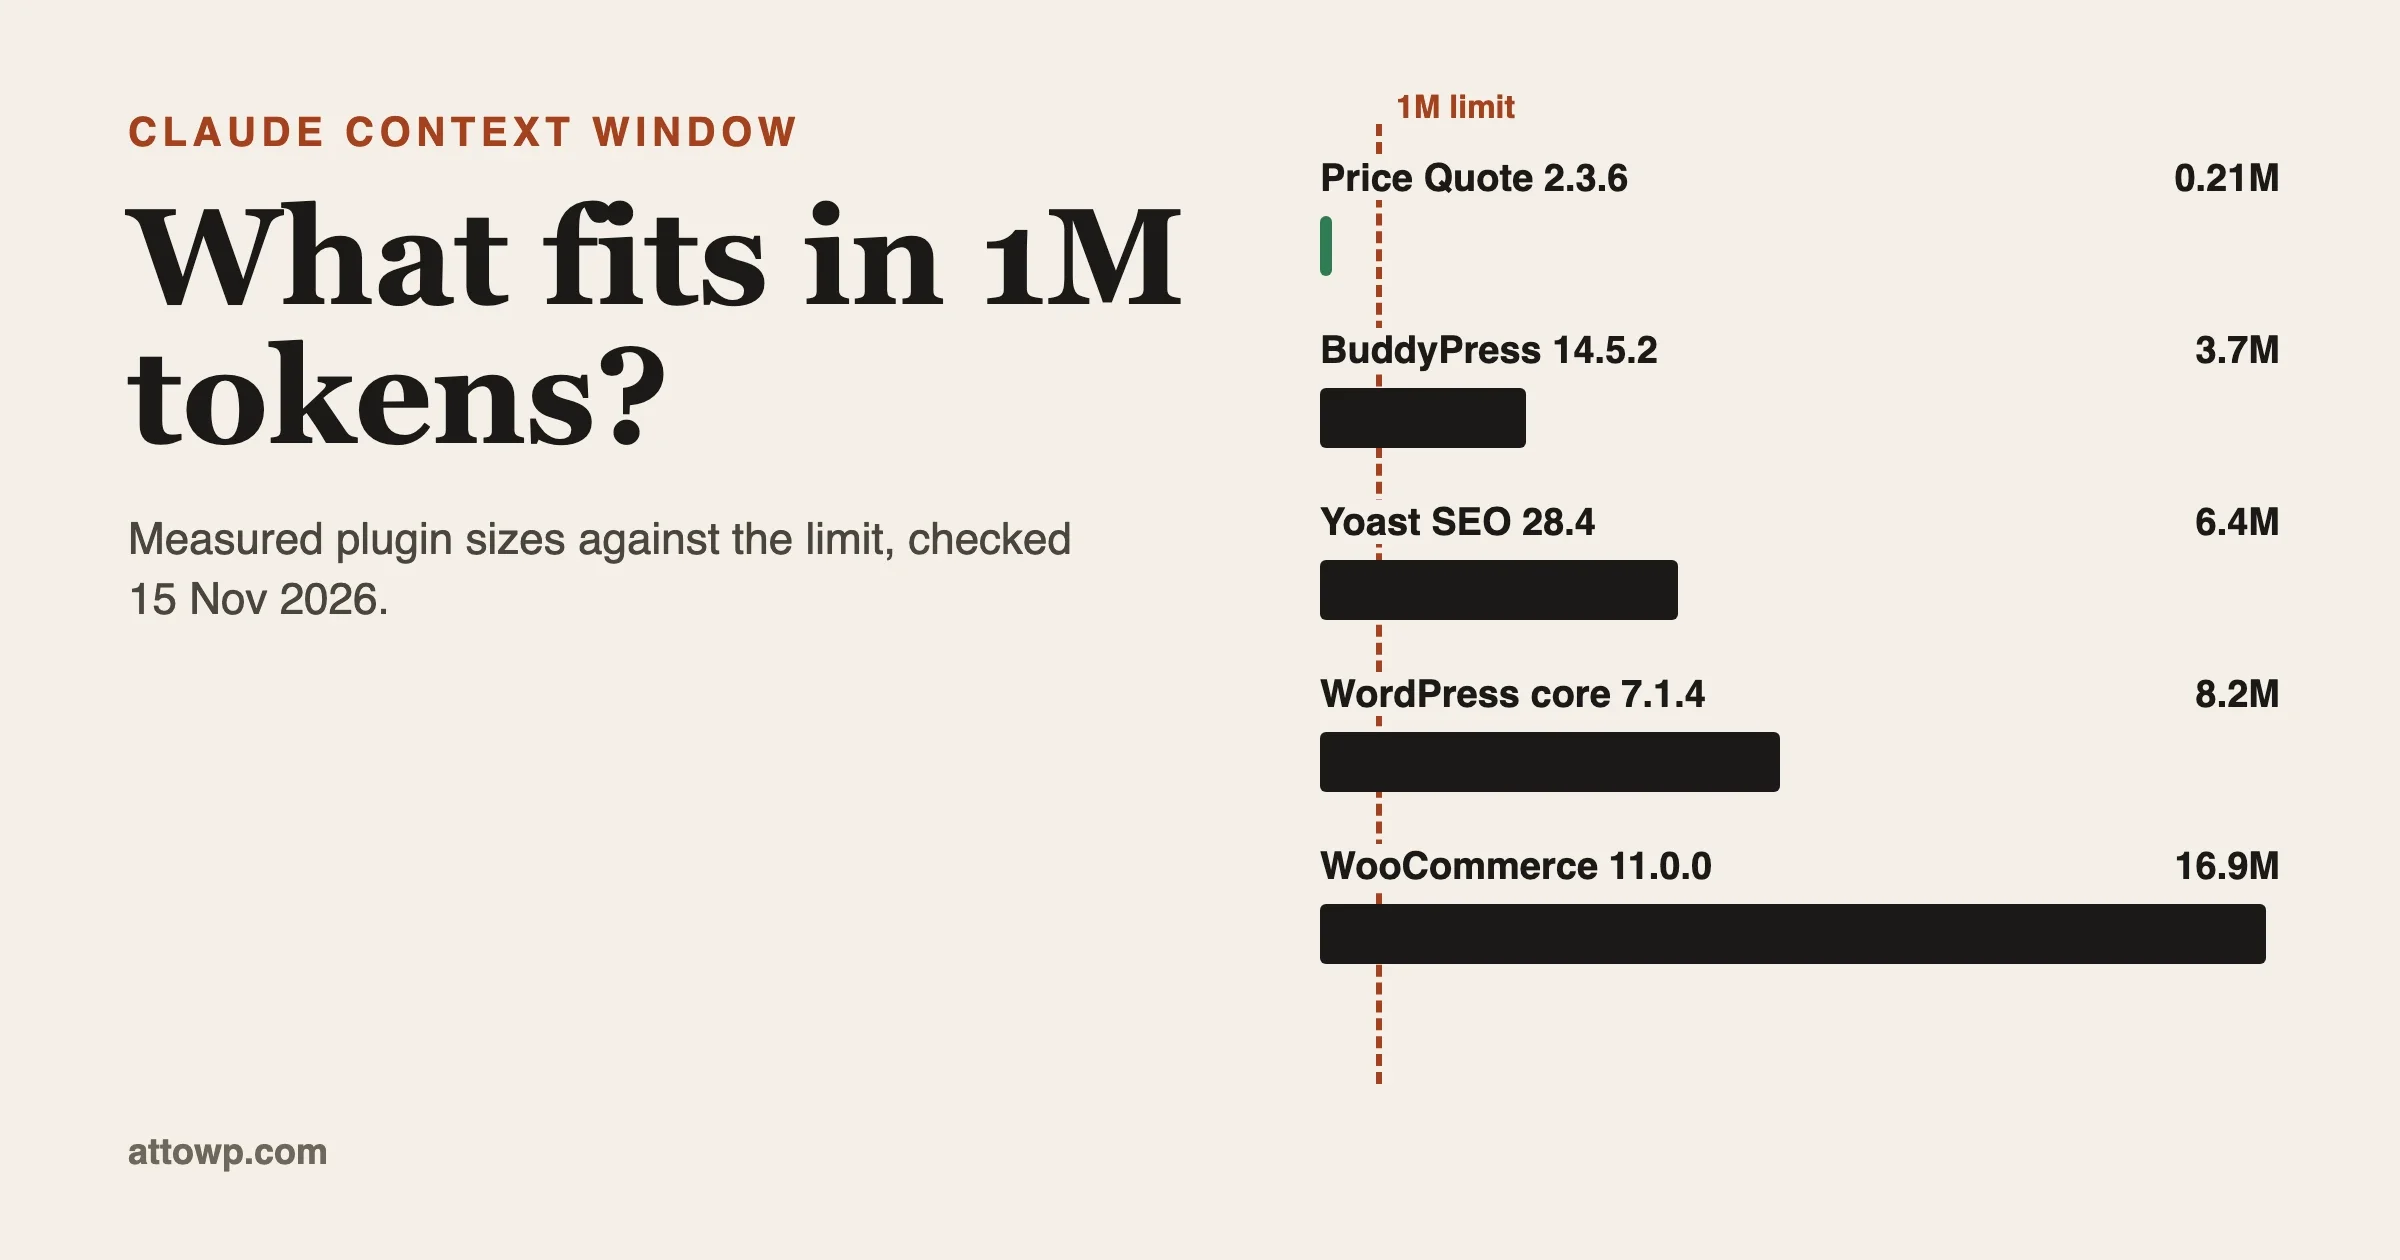
WooCommerce Price Quote 2.3.6 | 0.54 MB | about 0.21M | Yes, with room for a long chat |
BuddyPress 14.5.2 | 9.2 MB | about 3.7M | No |
Yoast SEO 28.4 | 15.9 MB | about 6.4M | No |
WordPress core 7.1.4, PHP only | 20.6 MB | about 8.2M | No |
WooCommerce 11.0.0 | 42.3 MB | about 16.9M | No |
Even at a looser 4 characters per token, BuddyPress would need about 2.3M tokens. The rule of thumb we now use: a plugin under roughly 2 MB of packed source is a candidate for loading whole, and you still want headroom for your questions, the model’s answers and thinking.
Our March post said Jetpack, Yoast SEO and WooCommerce extensions fit in one window. After measuring, Yoast does not, and neither does WooCommerce itself. We got that wrong then, and the table above is what we stand behind.
Does WordPress core fit?
No. We counted the PHP files in an unmodified WordPress 7.1.4 tree, excluding wp-content: 1,315 files, 617,676 lines and 20.6 MB. Stripping comment lines and blank space brings it to about 13.1 MB. Neither version gets under 1M tokens at any plausible ratio. You can load a slice of core, such as a single subsystem, but not the whole tree.
Pick the slice deliberately. The REST API classes in wp-includes, or the files that define the hooks your plugin touches, are a better fit than a blind dump of wp-includes.
When does long context beat retrieval for WordPress code?
Long context wins when the answer depends on seeing many files together. Retrieval wins when the answer sits in a few files and the codebase is big.
Task | Better fit | Why |
|---|---|---|
Trace user input to a database call across files | Long context | The path crosses files a search might not rank together |
List every AJAX handler and its capability check | Long context | You need all of them, not the top five |
Write docs for every public hook in a plugin | Long context | Completeness is the goal |
Fix one bug in one template | Retrieval or a plain file paste | The relevant code is a few kilobytes |
Work in WooCommerce core or WordPress core | Retrieval | The codebase is far beyond 1M |
Many small questions over the same code, all day | Long context plus caching, or retrieval | Cost per question decides it |
Anthropic’s own guidance on retrieval gives a useful anchor. In its contextual retrieval write-up, it says that if a knowledge base is smaller than 200,000 tokens, about 500 pages, you can include the whole thing in the prompt and skip retrieval. Past that, retrieval earns its keep, and the same post reports that adding context to chunks cut the top-20 retrieval failure rate by 35%, or 67% with BM25 and reranking added.
1M tokens moves that line out five times. It does not remove it.
The other reason to hold back is context rot. The context windows page states that as token count grows, accuracy and recall degrade, and that curating what sits in the window matters as much as how much space you have. A 900K prompt is allowed. It is not automatically a good idea. A focused 150K prompt with the right files often beats a full dump.
How much does a 1M-token prompt cost?
Input tokens cost the base rate, whatever the prompt length, on Fable 5.2, Opus 5.5 and Sonnet 5.5. The pricing page says a 900K-token request is billed at the same per-token rate as a 9K request. Haiku 5.5 is priced by prompt length: $0.10 per million input tokens up to 100,000 tokens, and $0.50 above that.
Here is one request with an 800,000-token prompt, input only, no cache, using the prices above. Output and thinking tokens are extra.
Model | Input cost, one request | Ten questions, no cache |
|---|---|---|
Fable 5.2 | $6.40 | $64.00 |
Opus 5.5 | $3.20 | $32.00 |
Sonnet 5.5 | $1.60 | $16.00 |
Haiku 5.5 (over 100K rate) | $0.40 | $4.00 |
If you ask ten questions in separate requests and resend the plugin every time, you pay for it ten times. That is the bill that surprises people. Prompt caching exists to fix it.
How does prompt caching change the cost?
It turns the repeated part of your prompt into a cheap read. You mark the packed plugin as cacheable, pay a one-time write price, and pay a small read price on every later request that starts with the same prefix.
From the pricing and prompt caching pages, per million tokens:
Model | Base input | 5-minute cache write | Cache read |
|---|---|---|---|
Fable 5.2 | $8 | $10 | $0.20 |
Opus 5.5 | $4 | $5 | $0.20 |
Sonnet 5.5 | $2 | $2.50 | $0.10 |
Haiku 5.5 (over 100K) | $0.50 | $0.625 | $0.05 |
A 1-hour cache write costs more, $8 per million on Opus 5.5, and is worth it when your questions are spread out. The default lifetime is 5 minutes, and each hit refreshes it at no extra cost.
For the same 800,000-token plugin on Opus 5.5, the first request pays $4.00 to write the cache. Each follow-up that hits it pays $0.16 for the cached part. Ten questions cost $4.00 plus nine reads of $0.16, which is $5.44, against $32.00 uncached. On Sonnet 5.5 the same session comes to $2.72 against $16.00.
Three rules decide whether that saving shows up:
- Put the packed plugin first in the request, then your question. The cache matches an exact prefix, built in the order tools, system, messages.
- Keep tool definitions, thinking settings and the effort setting steady. The caching docs say changing tool definitions invalidates the cache from tools onward, and changing thinking or effort invalidates the messages part.
- Check
cache_read_input_tokensin the response. If it andcache_creation_input_tokensare both 0, nothing was cached.
The minimum cacheable prompt on the 5.5 models is 512 tokens, so a plugin of any size qualifies.
How do you load a plugin into a prompt?
Pack it into one file with a header per file, count the tokens, then send it as a cached block. Both snippets below follow the docs; the packing script is the one we ran for the table above.
Checked on 15 Nov 2026. The packer is plain bash.
#!/usr/bin/env bash
# Usage: ./pack.sh path/to/plugin > plugin-context.txt
cd "$1" || exit 1
find . -type f \( -name '*.php' -o -name '*.js' -o -name '*.css' -o -name 'readme.txt' \) \
  -not -path './vendor/*' -not -path './node_modules/*' -not -path './tests/*' \
  -not -path './build/*' -not -path './languages/*' -not -name '*.min.*' | sort |
while read -r f; do
  printf '\n===== FILE: %s =====\n' "$f"
  cat "$f"
done
Count first, so you know before you pay. This uses the Anthropic Python SDK.
<pre class="wp-block-code"><code class="language-python">import anthropic
client = anthropic.Anthropic() code = open(“plugin-context.txt”, encoding=”utf-8”).read()
count = client.messages.count_tokens( model=”claude-opus-5-5”, messages=[{“role”: “user”, “content”: code}], ) print(count.input_tokens)</code></pre>
Then send it with a cache marker on the plugin block and your question after it.
response = client.messages.create(
    model="claude-opus-5-5",
    max_tokens=4096,
    messages=[{
        "role": "user",
        "content": [
            {"type": "text", "text": code,
             "cache_control": {"type": "ephemeral"}},
            {"type": "text", "text": "List every AJAX handler, its capability "
             "check, and how it sanitizes input."},
        ],
    }],
)
print(response.usage.cache_creation_input_tokens,
      response.usage.cache_read_input_tokens)
Ask a bounded question. “List every AJAX handler and what each one checks” gets a usable table. “Review this plugin” gets an essay.
What does a large context do well on WordPress work?
It does best where the answer is spread across files. In our experience these are the four jobs worth the tokens.
Security passes. Tracing a request from a REST route or AJAX action to a query, through helper classes in other files, is the case a single-file paste cannot handle. Ask for findings with file and line, then check each one by hand. Treat the output as a lead list for a human reviewer, not as a verdict. If the code you load comes from outside your team, read our note on prompt injection in WordPress code and content, because instructions hidden in comments or readme files are part of the context too.
Onboarding onto inherited code. “Explain how licence activation works from the form to the stored result” is a whole-codebase question and a fair one for a freshly loaded plugin.
Reference docs. Hook and filter lists, REST endpoint tables and settings references come out far more complete when the model has seen every file.
Release notes from a diff. Load the plugin, add the git diff between tags, and ask for the changelog in your house format.
For running an agent against a live site, rather than pasting code into a prompt, see our guides on AI coding agents with WordPress Playground and MCP and MCP servers in WordPress and Astro development. Agent tools often keep context small on purpose, which is the opposite approach from this post, and it suits day-to-day edits better.
What can a large context not do?
It cannot run your code. A 1M window holds static text. How hooks fire on your site, what is in the database, and which other plugins are active only show up if you paste logs, Query Monitor output or traces next to the source.
It does not replace judgment on architecture. It also does not make the prompt safe: whatever you load can contain instructions, and a model with tools can act on them.
And it does not remove the need for tests. Static analysis of a loaded plugin is a good second pair of eyes. A failing PHPUnit test is evidence.
Common mistakes people report
Checked on 15 November 2026. These come from Anthropic’s own documentation and from open and closed issues on the Claude Code tracker. We did not find enough forum or Reddit threads on this topic to cite, so those are not used.
- Assuming every surface gives 1M. Chat on a paid plan lists 500K for Opus 4.8, Opus 4.7, Opus 4.6, Sonnet 4.6 and Fable 5, while the API and Claude Code give 1M for those models. Source: Anthropic’s help article.
- Sessions that behave like 200K after compaction. Users reported that auto-compaction fired near 200K on a 1M model (issue 50888), and that the window dropped to 200K after a compaction (issue 79092). Both issues are closed as of this check. Update your tool and watch the context meter instead of trusting the model name.
- Compaction throwing away detail you needed. A user reported the summary dropping the analysis they had just produced (issue 42590, closed). Write conclusions to a file as you go, and do not rely on the conversation to remember them.
- “Prompt is too long” on resume. A report on issue 92434, still open on 15 November, describes a resumed session failing because large instruction files were re-added and the window overflowed before compaction ran. Running a manual compact afterwards worked. Keep project instruction files lean.
- Believing a bigger window means better recall. Anthropic’s context windows page warns that accuracy and recall degrade as tokens grow. Put the files that matter most in the prompt, and ask narrow questions.
- Flat-rate assumptions on Haiku 5.5. Its price steps up above 100,000 prompt tokens, and a request over the line pays the higher rate even when part of its prompt is a cache hit. Source: the pricing page.
- Cache that never hits. Changing tool definitions or thinking settings between calls invalidates the cached prefix. Check the usage counters from the first two requests.
Which setup should you pick?
A short decision list, based on what we measured.
- Plugin under about 2 MB packed, several questions to ask: pack it, count tokens, cache it, and use Sonnet 5.5 or Opus 5.5. Sonnet 5.5 is half the input price of Opus 5.5 and is the sensible first try.
- One bug in one file: skip all this. Paste the file and the error.
- Plugin between 2 MB and 10 MB: load the folders involved in the question, such as includes/rest plus the main loader, rather than everything.
- WooCommerce, Yoast SEO or WordPress core: use an agent or retrieval tool that searches the tree. Loading the whole thing is not possible.
- Budget is tight: Haiku 5.5 is the cheapest per token, but only up to 100,000 prompt tokens. Above that the rate is five times higher.
None of our own products belong in this list. This is a prompting and cost question, not a plugin one.
FAQ
Is Claude’s context window really 1 million tokens?
Yes, for the four current models, according to the models overview checked on 15 November 2026. Maximum output is 128K tokens per request.
How many words or lines of code is 1M tokens?
About 555,000 words or 2.5 million characters on the current tokenizer, per the models overview. We do not give a lines-of-code figure, because it depends on how your code is written. Pack your own plugin and count it.
Does the whole of WordPress core fit in 1M tokens?
No. The PHP in WordPress 7.1.4, excluding wp-content, is 20.6 MB in 1,315 files, and that is roughly 8.2M tokens at the docs’ ratio.
Is long context more expensive per token?
Not on Fable 5.2, Opus 5.5 or Sonnet 5.5. Haiku 5.5 charges more per token once a prompt passes 100,000 tokens. Longer prompts still cost more in total because they have more tokens.
Does prompt caching work with the 1M window?
Yes. The pricing page says caching and batch discounts apply at standard rates across the full window. Cache reads on Opus 5.5 and Sonnet 5.5 cost 0.05 times the base input price.
Do I need a beta header for 1M context?
Not on the API. The context windows page says 1M is the default for every model that has it, with no beta header.
Should I use long context or RAG for a WordPress plugin?
Use long context for whole-plugin questions on a codebase that fits. Use retrieval when the code is bigger than the window or when you ask many unrelated small questions. Anthropic’s own rule of thumb is that under 200,000 tokens you can skip retrieval.
Can Claude find every vulnerability in my plugin if I load all of it?
No. It gives you a lead list worth checking. Confirm each finding by hand, and use a published advisory feed for known issues in third-party code.
Where this leaves WordPress developers
The 1M window is real, and on current models it is priced fairly. What it does is move whole-plugin analysis from “impossible” to “a few dollars and a bash script” for plugins under a couple of megabytes. It does not make WordPress core or the big commerce plugins loadable, and it does not remove the need to ask narrow questions.
Measure your own plugin with the packer, count the tokens, cache the prefix, and keep your question specific. If the numbers say it does not fit, that is a sign to use a retrieval-based agent instead. For a wider view of the tools around this, our AI coding tools comparison and our guide to AI coding for WordPress plugins cover the workflow side.
No comments yet