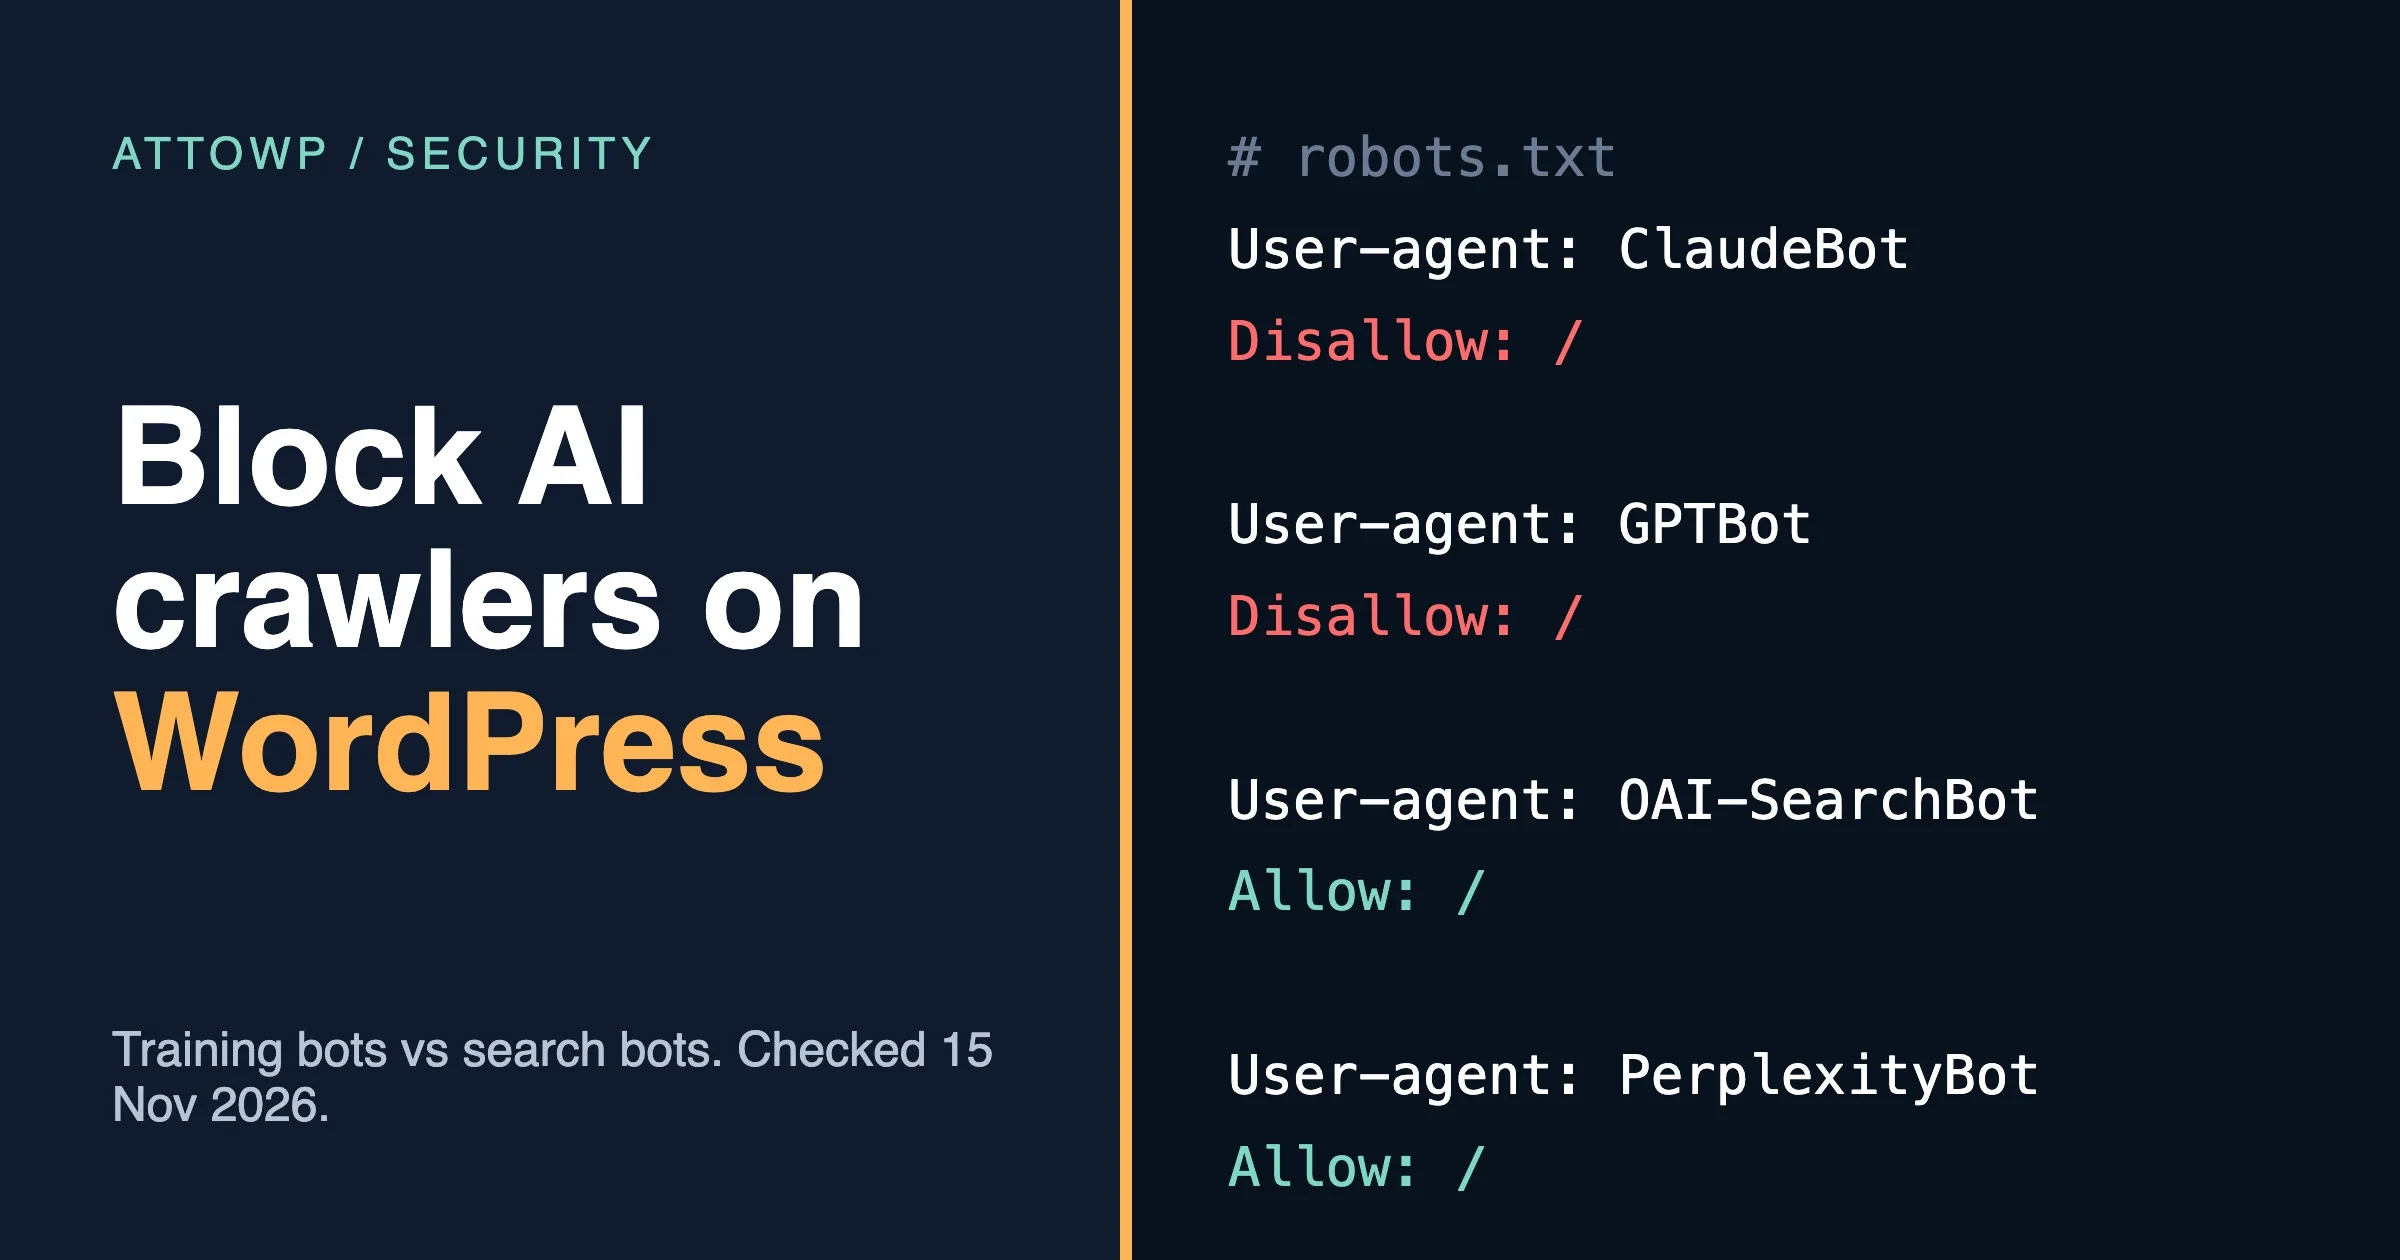
To block ClaudeBot on WordPress, add two lines to your robots.txt: User-agent: ClaudeBot followed by Disallow: /. Anthropic says its bots honour robots.txt, and that is the method it asks site owners to use. Do not stop at that one rule, though. Anthropic runs three bots, ClaudeBot for training, Claude-User for answers requested by a person and Claude-SearchBot for search, and each one has a different cost when you block it. We checked every vendor page named in this guide on 15 Nov 2026.
The short version: blocking training crawlers (ClaudeBot, GPTBot, CCBot, Google-Extended, Applebot-Extended, meta-externalagent) costs you little. Blocking search and answer bots (OAI-SearchBot, Claude-SearchBot, PerplexityBot, meta-webindexer) removes you from the answers those products give, which is where a growing share of readers now start. Below we cover the user agents, which ones listen to robots.txt, how to apply rules in WordPress, how Cloudflare fits in, and the mistakes people keep reporting.
Which AI crawlers should I block?
Block the bots that only collect training data, and think hard before blocking the ones that fetch pages to answer a question. Every major vendor now publishes separate bots for training, search and user-requested fetching, so you can say yes to one and no to another. This table lists the user agents and robots.txt tokens as the vendors document them today.
Operator | Token | What it does | Honours robots.txt? |
|---|---|---|---|
Anthropic | ClaudeBot | Collects content that may be used for model training | Yes |
Anthropic | Claude-SearchBot | Indexes pages to improve search answers | Yes |
Anthropic | Claude-User | Fetches a page when a person asks Claude about it | Yes, per Anthropic |
OpenAI | GPTBot | Crawls content that may be used for training | Yes |
OpenAI | OAI-SearchBot | Surfaces sites in ChatGPT search results | Yes |
OpenAI | ChatGPT-User | Visits a page for a ChatGPT or custom GPT user action | Not guaranteed, user-initiated |
Google-Extended | Control token for Gemini training and grounding | Yes, it is a robots.txt token only | |
Perplexity | PerplexityBot | Surfaces and links sites in Perplexity search | Yes |
Perplexity | Perplexity-User | Fetches a page when a user asks | Generally ignores it |
Common Crawl | CCBot | Builds the open Common Crawl dataset | Yes |
Apple | Applebot-Extended | Opt-out token for generative model training | Yes, token only |
Meta | meta-externalagent | Training foundation models and indexing | Yes |
Meta | meta-webindexer | Meta AI search quality | Yes |
Meta | meta-externalfetcher | Fetches links at a user’s request | May bypass it |
Sources, all checked on 15 Nov 2026: Anthropic, OpenAI, Google common crawlers, Perplexity, Common Crawl, Apple and Meta.
What does each vendor say about its bots?
Anthropic: ClaudeBot, Claude-User and Claude-SearchBot
Anthropic documents three bots. ClaudeBot gathers web content that could contribute to training. Claude-User retrieves a page when someone asks Claude a question, and Anthropic warns that disabling it may reduce your visibility for user-directed web search. Claude-SearchBot analyses pages to improve search result quality, and disabling it may reduce your visibility in search answers.
Anthropic states that its bots honour robots.txt, support the non-standard Crawl-delay directive and will not try to bypass CAPTCHAs. It also says that blocking by IP address may not work reliably, because it stops the bot from reading your robots.txt in the first place. Its support page lists published IP ranges you can use to confirm that a request really came from Anthropic.
One change is worth knowing about. Anthropic’s page says that as of 30 October 2026 it has begun recognising a machine-readable “no AI training” preference signal, based on an IETF AI Preferences (aipref) working group draft, and that it is rolling this out over time. The same page says a robots.txt rule that names ClaudeBot takes priority over the general signal. If you want a firm answer, name the bot.
OpenAI: GPTBot, OAI-SearchBot and ChatGPT-User
OpenAI says each setting is independent. You can allow OAI-SearchBot so your pages can appear in ChatGPT search and disallow GPTBot so your content is not used for training. OpenAI also notes that sites opted out of OAI-SearchBot will not be shown in ChatGPT search answers, though they can still appear as navigational links, and that a robots.txt change can take around 24 hours to take effect.
ChatGPT-User is different. OpenAI describes it as visiting a page when a user asks ChatGPT or a custom GPT something, says it is not used for automatic crawling or to decide whether content appears in Search, and says that because a person initiated the visit, robots.txt rules may not apply. A third agent, OAI-AdsBot, only visits pages submitted as ads and its data is not used to train foundation models. OpenAI publishes IP lists for each bot as JSON files, which is how you verify traffic.
Google: Google-Extended is a token, not a bot
Google-Extended has no HTTP user agent string of its own. Crawling is done with Google’s existing user agents, and the robots.txt token only controls how that content is used. Google says it governs whether content may be used for future Gemini model training and for grounding in Gemini Apps and Grounding with Google Search on Vertex AI. It does not affect inclusion in Google Search and is not a ranking signal.
That has two practical consequences. You cannot block Google-Extended at the server, because there is nothing to match in the user agent. And disallowing it does not remove you from AI Overviews or AI Mode. Google’s AI features documentation says to limit what Search shows from your pages with nosnippet, data-nosnippet, max-snippet or noindex. Google also states that it intends to support the AIPREF training signal in early 2027, and that its user-triggered fetchers generally ignore robots.txt because a person asked for the fetch.
Perplexity, Common Crawl, Apple and Meta
Perplexity says PerplexityBot surfaces and links sites in its search results and is not used to crawl content for foundation models. Perplexity-User supports user actions and, because a user requested the fetch, generally ignores robots.txt.
Common Crawl identifies CCBot as CCBot/2.0, asks you to use User-agent: CCBot with Disallow: /, and warns that other crawlers falsely claim to be CCBot. It now runs on dedicated IP ranges with reverse DNS so you can check a log entry.
Apple says Applebot crawl data powers search features in Spotlight, Siri and Safari, and that data may also help train Apple foundation models. Disallowing Applebot-Extended opts out of training, but regular Applebot can still crawl, and your content stays discoverable in Apple search features. Apple adds that if your robots.txt does not mention Applebot but does mention Googlebot, Applebot follows the Googlebot rules, and that Applebot ignores crawl-delay.
Meta lists four bots. meta-externalagent crawls for training foundation models or improving products by indexing content. meta-webindexer improves Meta AI search, and Meta says allowing it helps Meta AI cite and link to your content. meta-externalads serves advertising uses. meta-externalfetcher fetches links at a user’s request and, in Meta’s words, may bypass robots.txt. Meta also says its facebookexternalhit crawler might bypass robots.txt for security or integrity checks, and allows up to 24 hours for robots.txt changes to apply.
How do I block AI crawlers in WordPress robots.txt?
WordPress serves a virtual robots.txt when no physical file exists, and you can edit it with the robots_txt filter. The filter takes two arguments, the current output and a boolean for whether the site is public, and has existed since WordPress 3.0.0 according to the developer reference. Put this in a small plugin or an mu-plugin, not in a theme, so a theme switch does not drop your rules.
Checked on 15 Nov 2026 against the developer.wordpress.org hook reference. This version blocks training crawlers only and leaves search and answer bots alone.
<?php
/**
 * Plugin Name: Block AI training crawlers
 */
add_filter( 'robots_txt', function ( $output, $is_public ) {
	if ( ! $is_public ) {
		return $output;
	}

	$training_bots = array(
		'ClaudeBot',
		'GPTBot',
		'CCBot',
		'Google-Extended',
		'Applebot-Extended',
		'meta-externalagent',
	);

	$rules = "\n";
	foreach ( $training_bots as $bot ) {
		$rules .= "User-agent: {$bot}\nDisallow: /\n\n";
	}

	return $output . $rules;
}, 10, 2 );
After saving, open /robots.txt in a browser and confirm the rules appear. If they do not, a physical robots.txt file is almost certainly in your web root. The web server serves a physical file directly, so WordPress never builds the virtual one and the filter never runs. Delete or rename the file, or edit it by hand.
The hand-edited version
If you prefer a physical file, this is the same policy written out. It adds the search and answer bots as a commented block you can enable if you decide you do not want to appear in those products.
# Checked on 15 Nov 2026 against each vendor's documentation
User-agent: ClaudeBot
Disallow: /

User-agent: GPTBot
Disallow: /

User-agent: CCBot
Disallow: /

User-agent: Google-Extended
Disallow: /

User-agent: Applebot-Extended
Disallow: /

User-agent: meta-externalagent
Disallow: /

# Search and answer bots. Uncomment only if you accept losing AI citations.
# User-agent: OAI-SearchBot
# Disallow: /
# User-agent: Claude-SearchBot
# Disallow: /
# User-agent: PerplexityBot
# Disallow: /
# User-agent: meta-webindexer
# Disallow: /
Each vendor reads its own group, so you do not need a wildcard rule. Do not add Disallow: / under User-agent: * to catch everything. That blocks Googlebot and Bingbot as well and takes you out of search.
Is a plugin better than editing robots.txt myself?
A plugin is fine for most sites, as long as you understand what it edits. The free Block AI Crawlers plugin on WordPress.org was at version 1.6.3, updated 1 November 2026, with 2,000+ active installs and a 4.4-star average from 8 ratings when we checked on 15 Nov 2026. Its block list is generated from the ai.robots.txt project. It only works with WordPress’s virtual robots.txt, and the plugin page says you cannot activate it if a physical file exists. Reviewers from the last year praise its simplicity and complain about the fixed list, so you cannot edit it to allow a bot you want.
Our view: if you want a tailored policy (block training, allow search), the twenty-line filter above gives you control and no dependency. If you want a maintained list with no thought, the plugin does that job.
Do AI crawlers actually obey robots.txt?
The documented training and search bots from the vendors above say they do, and the vendors publish IP ranges so you can check. The documented user-triggered fetchers (ChatGPT-User, Perplexity-User, meta-externalfetcher, Google’s user-triggered fetchers) say they may not, because a person asked for that page. Robots.txt is also a request, not an enforcement tool, so an unlisted scraper can ignore it. Cloudflare’s own documentation puts it plainly: compliance is voluntary.
That is why robots.txt alone is a statement of policy. If a crawler you blocked keeps showing up, check three things in this order: whether the user agent really is the vendor’s (verify the IP against the published list), whether your robots.txt is the one being served, and whether the request is a user-triggered fetch that was never bound by it.
How do I block bots at the server level?
Match the user agent and return 403 for training crawlers that you want stopped regardless of robots.txt. Server rules are the only thing that stops a crawler that ignores your file, but they come with a cost. Anthropic notes that blocking can stop its bot from reading robots.txt at all, so keep /robots.txt reachable and treat the server rule as a backstop. Google-Extended and Applebot-Extended cannot be matched here, because they are tokens with no user agent of their own.
Checked on 15 Nov 2026. Apache with mod_rewrite, in .htaccess above the WordPress block:
<IfModule mod_rewrite.c>
RewriteEngine On
RewriteCond %{REQUEST_URI} !^/robots\.txt$
RewriteCond %{HTTP_USER_AGENT} (ClaudeBot|GPTBot|CCBot|meta-externalagent) [NC]
RewriteRule .* - [F,L]
</IfModule>
Nginx, with the map blocks in the http context and the if inside your server block:
map $http_user_agent $ai_training_bot {
    default 0;
    ~*(ClaudeBot|GPTBot|CCBot|meta-externalagent) 1;
}
map $uri $ai_training_block {
    default $ai_training_bot;
    /robots.txt 0;
}

server {
    # ...
    if ($ai_training_block) {
        return 403;
    }
}
Test with curl -A "GPTBot" -I https://your-site.example/ and expect a 403, then run the same command with a normal user agent and expect a 200. A user agent is trivial to fake in both directions, so a bot that wants in can send a browser string. For a real wall you need IP verification or a service that does bot detection.
What do Cloudflare’s AI bot controls do now?
Cloudflare has two related features, and their names have changed, so check your dashboard. AI Crawl Control (formerly AI Audit) is available on all plans, shows which AI services reach your content and lets you set Allow or Block per crawler. You can configure the response returned when blocking. On the free plan it detects crawlers from their user agent strings, and Cloudflare says paid plans use Bot Management detection for a more thorough match. A Directives tab tracks robots.txt health and shows which crawlers violate your rules, and pay per crawl is in private beta.
The second feature is AI Crawler and Agent access policies, under Security, Settings. It sorts traffic by behaviour into Search, Agent and Training, and each gets an action: Block, Block on pages with ads, Allow, or for Training only, Disallow. With Bot Preference Sync on, Cloudflare prepends managed robots.txt directives and its Content Signals Policy to your own file, and Disallow also blocks training crawlers at the edge. Cloudflare says mixed-purpose crawlers, used for both Search and Training, are excluded from that edge block, and that new domains default to Allow for all three.
The warning from this area is about breadth. A managed IT provider’s report, written up by Something Inc on 13 August 2026, describes turning on Cloudflare’s AI crawler blocking and unintentionally blocking Google, with about two weeks to recover after the block was lifted. That is one account, not a confirmed bug, but it matches the lesson: after any bot setting changes, fetch your pages as Googlebot with Search Console’s URL Inspection and read the live robots.txt.
What does blocking cost me in AI search?
Blocking search and answer bots removes you from the answers those products write, and the vendors say so themselves. OpenAI says sites opted out of OAI-SearchBot will not be shown in ChatGPT search answers. Anthropic says disabling Claude-SearchBot may reduce visibility and accuracy in search results, and disabling Claude-User may reduce visibility for user-directed search. Meta says allowing meta-webindexer helps it cite and link to you. Perplexity recommends allowing PerplexityBot so your site appears in its results.
Training bots are different. Blocking them stops future model training on your pages in the cases where the vendor honours the rule, and it does not affect search results or AI citations at the vendor’s search products. The two groups are separate on purpose.
Goal | Block | Allow | Cost |
|---|---|---|---|
Keep content out of training, stay in AI answers | ClaudeBot, GPTBot, CCBot, Google-Extended, Applebot-Extended, meta-externalagent | OAI-SearchBot, Claude-SearchBot, PerplexityBot, meta-webindexer, user fetchers | Low |
Stay out of AI answers entirely | All of the above plus the search bots | Googlebot, Bingbot | You lose AI citations and referral clicks |
Cut server load only | Rate limit or 403 the heaviest bots in your logs | Everything else | Needs log review |
Paywalled or members-only content | Everything, plus login and server rules | Nothing | None, robots.txt is not security |
Our default for a publisher or a business site is the first row. Readers who ask an assistant for a recommendation are exactly the readers you want, and being quoted there is worth more than the training exclusion costs you. If you want to see what AI traffic you already get before deciding, read our guide on how much traffic you actually get from AI first.
Will blocking AI crawlers affect Google rankings or AI Overviews?
Blocking Google-Extended does not change your Google Search ranking, according to Google, and it does not remove you from AI Overviews. AI Overviews and AI Mode are part of Search, so Googlebot access and the snippet controls decide what is shown. If you want to limit what appears, nosnippet and max-snippet reduce what Search can quote, at the price of less visible snippets in normal results too. One reviewer of the Block AI Crawlers plugin on 10 July 2026 asked for a way to block Google’s AI Overview. A robots.txt plugin cannot do that, for the reason above.
Our related piece on AI Overviews and publisher revenue covers the tradeoff between snippet limits and visibility in more detail.
How do I check which crawlers are hitting my site?
Read your access log by user agent. A one-liner on a typical Linux host gives you a ranked list of AI bot hits:
# Checked on 15 Nov 2026. Adjust the log path for your host.
grep -iE "claudebot|claude-user|claude-searchbot|gptbot|oai-searchbot|chatgpt-user|perplexity|ccbot|applebot|meta-external|meta-webindexer" \
  /var/log/nginx/access.log \
  | awk -F'"' '{print $6}' | sort | uniq -c | sort -rn | head -20
Then verify any heavy hitter against the vendor’s published IP list (openai.com/gptbot.json, perplexity.ai/perplexitybot.json and so on) or reverse DNS for Applebot and CCBot. Spoofed user agents are common, and Common Crawl says so on its own page. On shared hosting without log access, Cloudflare’s AI Crawl Control dashboard gives you the same view, and it even lists robots.txt violations per crawler.
Common mistakes people report
These are the recurring problems from plugin reviews, vendor notes and published incident write-ups we found. Checked on 15 Nov 2026. We could not find a large body of forum or GitHub threads on this subject, so the list is short and we say where each item comes from.
- A physical robots.txt silently overrides the plugin. The Block AI Crawlers plugin page states it only works with WordPress’s virtual file, and a reviewer in May 2025 said they had to rename a hand-typed file before it worked. Source: plugin page and reviews.
- Testing a cached file. The same plugin FAQ says robots.txt can be cached by the web server, a plugin or a CDN such as Cloudflare, so a change may not show until the cache expires. Test with
curland read the headers. - Expecting a robots.txt plugin to stop Google AI Overviews. A July 2026 review on the plugin page asks for exactly that. Google’s documentation points to
nosnippet,data-nosnippet,max-snippetornoindexinstead. - A fixed block list that cannot be edited. A 23 July 2026 review calls it too blunt because you cannot allow a bot you want. A custom filter fixes that.
- A bot toggle that also blocks Googlebot. The Something Inc write-up (13 August 2026) describes one site losing organic traffic after a crawler-blocking setting in Cloudflare. Re-check Search Console after any change. Source: Something Inc.
- Believing a block covers user-initiated fetches. OpenAI, Perplexity, Meta and Google each say their user-triggered fetchers may ignore robots.txt. If you need those stopped, you need a server or firewall rule, and you will also stop real people using those tools on your page.
What should my setup look like in practice?
Work in layers, and stop at the first layer that meets your goal. Each extra layer adds maintenance.
- Decide first. Training only, or training plus search. Write it down so the next person does not guess.
- robots.txt. Use the filter or a hand-written file with named groups. Never touch the wildcard group.
- Verify. Fetch
/robots.txt, check it is the one you wrote, and test it with Search Console to confirm Googlebot is still allowed. - Cloudflare, if you use it. Review AI Crawl Control. Choose Allow or Block per crawler, and use Bot Preference Sync only if you want Cloudflare to write robots.txt lines for you.
- Server rules, only for repeat offenders. A short list of user agents that your log shows ignoring robots.txt.
- Review every quarter. Vendors add bots and rename them. Older guides list far fewer bots than the vendors document today.
If you run a site where leaked data is a concern, not just copying, remember that robots.txt and user-agent rules protect nothing. Private content needs authentication. For how AI agents that visit your pages can be steered by what they read, see our guide to AI prompt injection in WordPress.
FAQ
How do I block ClaudeBot from my WordPress site?
Add User-agent: ClaudeBot and Disallow: / to robots.txt, either with the robots_txt filter or in a physical file. Anthropic says its bots honour robots.txt and recommends this method over IP blocking.
Is ClaudeBot the same as Claude-User?
No. ClaudeBot collects content that may contribute to training. Claude-User fetches a page when a person asks Claude a question, and Claude-SearchBot supports search quality. Blocking ClaudeBot does not block the other two.
Does blocking GPTBot remove me from ChatGPT search?
No. OpenAI says GPTBot and OAI-SearchBot are independent. Blocking GPTBot signals that content should not be used for training. Blocking OAI-SearchBot is what keeps you out of ChatGPT search answers.
Does Google-Extended stop AI Overviews?
No. Google says Google-Extended governs Gemini training and grounding, does not affect Search and is not a ranking signal. For AI Overviews, use the snippet controls Google lists.
Can I block Google-Extended or Applebot-Extended with .htaccess?
No. Both are robots.txt tokens, not separate user agents, so there is nothing to match in a server rule.
Will robots.txt stop every AI scraper?
No. It is voluntary. Vendors that publish bots say they honour it, user-triggered fetchers may not, and scrapers that hide behind a browser user agent never read it.
Do I need Cloudflare to block AI crawlers?
No. robots.txt and server rules work without it. Cloudflare adds per-crawler controls, robots.txt violation tracking and edge blocking, which help when your host gives you no log access.
Should I block, allow or split?
For most WordPress sites, split. Block the training crawlers by name, leave the search and answer bots alone, verify that Googlebot is still allowed, and review the list every quarter. Block everything only if you sell content that AI answers would replace, and then back it with real access control, because robots.txt is a request that honest bots follow and nothing more. Whatever you choose, read your own robots.txt back after each change. Most of the pain people report comes from a file they assumed was live and was not.
No comments yet